What Google Cloud actually built
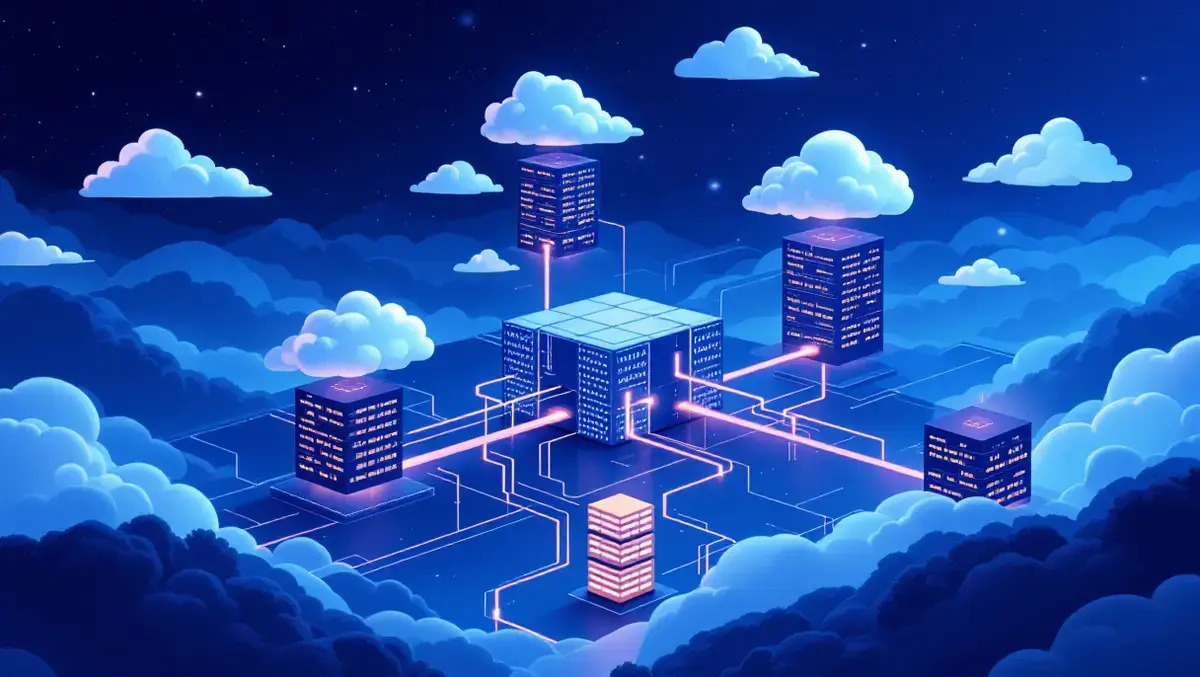
Google Cloud now lets BigQuery run federated queries directly against data cataloged in Databricks Unity Catalog, Snowflake Horizon Catalog, and AWS Glue Data Catalog. In a documented example, a single SQL query joined native BigQuery sales data with Snowflake customer records, Databricks product data, and AWS Glue store locations in one statement, using four-part table paths to address each remote source. The result could be grouped, ranked by revenue, and even saved as a logical view that natural-language conversational analytics tools can query later.
This is a federated catalog connection built on Apache Iceberg's REST catalog standard, not a data movement product. BigQuery syncs schema and snapshot metadata from each external catalog on a user-set schedule, with a minimum refresh interval of 300 seconds, then reads the underlying Parquet data files straight from remote object storage using temporary credentials issued by the source platform at query time. Nothing about the source tables themselves needs to change for this to work.
How the federation actually runs under the hood
The mechanics matter for anyone evaluating this for production use. BigQuery does not call into a live Databricks cluster or a live Snowflake warehouse to execute the remote portion of a query. All query processing happens on Google Cloud compute, using the metadata BigQuery has synced and the raw files it reads directly from storage. Databricks and Snowflake compute sit idle during these federated reads, which is a meaningfully different architecture from a typical cross-platform query pushdown.
Large catalogs with hundreds of tables can take longer to complete a sync cycle, and if one cycle overruns its window, the next scheduled sync is skipped rather than queued. Engineers relying on near-real-time joins across platforms need to watch for that skip behavior directly in their pipeline monitoring, since a silently skipped sync produces stale results without an obvious error at query time. That makes this a feature best paired with explicit freshness checks on the join, not a drop-in replacement for a dedicated real-time pipeline where staleness has a defined business cost.
What this is not
It is worth being precise about the limits here, because the marketing framing of "query anything, anywhere" invites overreach. This federation connects catalogs that speak the Apache Iceberg REST standard, which means Databricks Unity Catalog, Snowflake Horizon Catalog, and AWS Glue specifically, not an arbitrary external database or a legacy on-premises warehouse. A team still running a proprietary data mart that has never adopted an open table format gets none of this benefit until that mart is migrated onto Iceberg or a format with an equivalent catalog interface.
That caveat narrows who benefits immediately. Organizations that have already standardized storage on open table formats, even across multiple compute vendors, are the ones positioned to use this on day one. Organizations still running closed, proprietary formats on one or more platforms have a prerequisite migration to complete before federated queries of this kind become available to them, which is itself a useful data point for anyone deciding how to prioritize an open-format migration already underway.
The compute bill still has to land somewhere
It is tempting to read "no data movement" as "no added cost," and that reading would be wrong. Every federated query that touches Databricks or Snowflake tables now runs its compute on Google Cloud, which means the spend that used to show up on a Databricks or Snowflake invoice for cross-platform analytics work now shows up on a BigQuery invoice instead. The total compute required to run the join has not gone away. It has simply relocated to whichever platform happens to host the query.
Finance and platform teams building cost models around this feature should treat it as a workload migration tool as much as an integration feature. A team that starts running its heaviest cross-platform reporting queries through BigQuery federation, rather than through Databricks or Snowflake compute, is effectively voting with its workload for which vendor gets that revenue. That vote is worth making deliberately rather than letting it happen by default because an analyst found the feature convenient.
A data residency wrinkle nobody asked for
Retrieved cross-cloud data gets cached in the region where the federated catalog resides, which reduces repeat network transfers but also means a copy of externally sourced data now sits inside Google Cloud's regional boundary, even though the design goal was to avoid copying data in the first place. Teams can check whether a given query actually used the cache by comparing cacheBytesRead against objectStorageBytesRead in BigQuery's job statistics, but that check has to be run deliberately rather than assumed.
Where the constraints/gcp.restrictNonCmekServices organization policy applies, BigQuery skips the cache entirely and reads from remote storage on every query, which avoids the residency question but at the cost of repeated cross-cloud transfer on every run. Security and compliance teams evaluating this feature for regulated data need to decide upfront which behavior they are getting, and confirm it rather than discover it after the connector is already in production. A single query against health, financial, or EU personal data deserves a written answer on where that data physically sat during the join, before the first production dashboard is built on top of it.
Why this changes the multi-warehouse calculus
Large enterprises routinely end up running Snowflake, Databricks, and BigQuery side by side after acquisitions, regional rollouts, or simple team-level tool choices that nobody centrally approved. The usual response has been an expensive, multi-year consolidation project aimed at getting everything onto one warehouse so that cross-platform joins stop requiring brittle ETL pipelines and duplicated copies of the same tables. Those projects routinely run over budget, in part because the business case rests on a cost that is easy to state but hard to measure precisely until the migration is already underway.
Federated access of this kind removes one of the strongest arguments for that consolidation. If BigQuery can already join live data across all three platforms without a copy step, the case for migrating Snowflake workloads onto Databricks, or vice versa, has to rest on something other than query convenience. That is a genuine shift in the build versus consolidate debate, and it arrived through a feature announcement rather than a strategic architecture review. Any consolidation business case still sitting in a backlog deserves a second look against this new baseline before anyone commits budget to it.
The decision now in front of data leaders
Before approving this for anything beyond ad hoc analyst queries, confirm which organization policies apply to cached cross-cloud data, and get an explicit answer on where compute cost for federated queries will land in next quarter's cloud bill. Both questions have concrete, checkable answers, and neither should be left to surface after the fact in a finance review once usage has already scaled past the pilot stage. Put a named owner on monitoring that cost line specifically, separate from general BigQuery spend, so a quiet migration of workload away from Snowflake or Databricks compute shows up as a visible trend rather than a surprise at renewal time.
Longer term, this is a reason to pause any warehouse consolidation business case that was built primarily around the cost of cross-platform joins. That specific cost just dropped for a meaningful set of use cases, and a consolidation project justified mainly on those grounds deserves a fresh look before anyone signs off on the multi-year timeline and budget it would otherwise require. The platforms themselves are converging on interoperability faster than most procurement cycles move, and that pace is worth building into any multi-year contract being negotiated right now.